Build an AI Model Router with Jev
Choose deterministic code, a fast model, a deeper model, or human review using bounded routing judgments.
On this page
What you’ll buildArchitecturePrerequisites and sample inputStep 1 — Prepare the evidenceStep 2 — Define the atomic questionsStep 3 — Read answers and apply a gateStep 4 — Keep execution separateRun itExpected fixture resultRead the probabilitiesFailure cases and production improvementsComplete codeWhat to test before shippingWhat you’ll build
Choose deterministic code, a fast model, a deeper model, or human review using bounded routing judgments. The result is a runnable decision pipeline, with a fixture mode for checking local behavior and a live mode for evaluating your own TypeSafe account. It prints a recommendation without performing external side effects.
Architecture
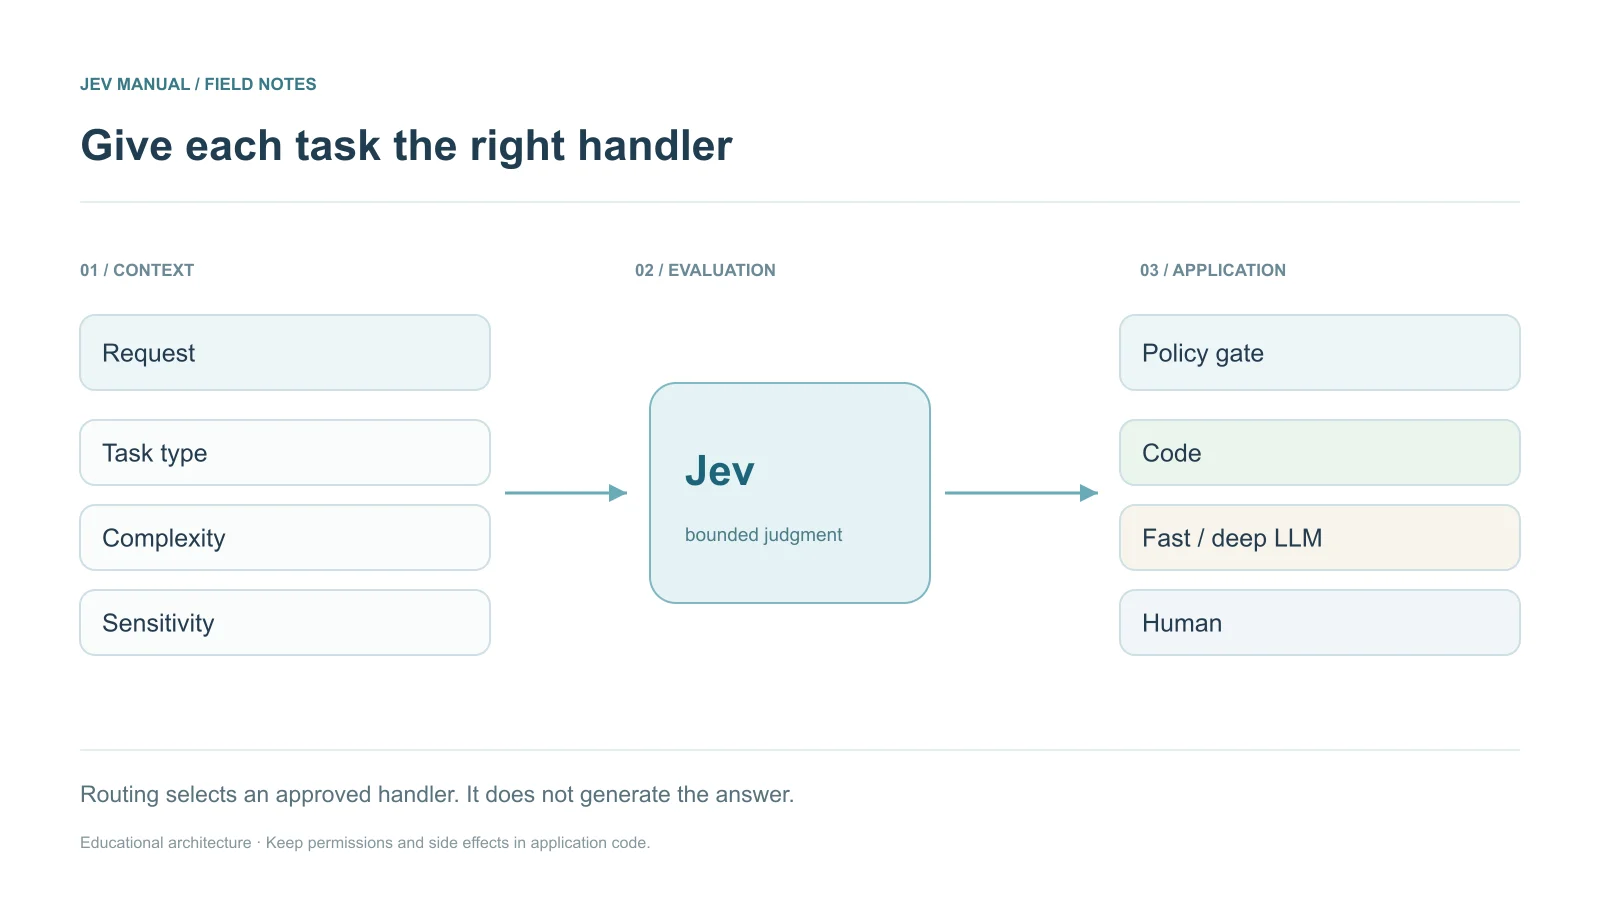
Request → Jev route + sensitivity → confidence and policy gate → approved handler
The labels describe work classes, not arbitrary URLs. Keep the mapping from labels to configured models in code. A route recommendation does not need to include provider credentials or a generation request.
Prerequisites and sample input
Use Python 3.10+; these standalone examples use only the standard library. Live evaluation also requires TYPESAFE_API_KEY in the environment. Download the complete script below rather than copying disconnected fragments.
{
  "request": "Explain why our retry policy doubles request volume during an outage.",
  "available_handlers": [
    "code",
    "fast",
    "deep",
    "human"
  ]
}
Step 1 — Prepare the evidence
Keep the input shape stable and distinguish verified application facts from user claims. The labels describe work classes, not arbitrary URLs. Keep the mapping from labels to configured models in code. A route recommendation does not need to include provider credentials or a generation request.
Step 2 — Define the atomic questions
{
  "route": {
    "type": "choice",
    "instructions": "Which handler best fits the requested work?",
    "criteria": {
      "code": "Exact deterministic computation",
      "fast": "Simple prose or familiar transformation",
      "deep": "Complex analysis or multi-step explanation",
      "human": "Missing context or consequential judgment"
    }
  },
  "sensitive": {
    "type": "noul",
    "instructions": "Does the request contain sensitive account or credential information?"
  }
}
The question names map outputs back to your code. They are not inference instructions. Put the actual judgment in instructions, and use criteria for category descriptions or ordered levels.
Step 3 — Read answers and apply a gate
The standalone script checks required answer keys, types, allowed categories, numeric ranges, and confidence. Missing or malformed data stops the decision path. The following action policy uses educational thresholds; none have been measured on your data.
def decide(answers, state):
    route = answers["route"]
    allowed = {"code", "fast", "deep", "human"}
    handler = route["choice"] if route["choice"] in allowed else "human"
    if route["confidence"] < .85 or answers["sensitive"]["noul"] >= .2:
        handler = "human"
    return {"handler": handler, "generation_executed": False}
Step 4 — Keep execution separate
The program prints a route or candidate result. A real executor must apply its own permissions, validation, idempotency, and confirmation requirements. A model label is evidence for a decision, not authorization to perform a consequential action.
Run it
Download the complete model-routing.py program. Then run:
python model-routing.py
# After configuring TYPESAFE_API_KEY, opt in to a live billed call:
python model-routing.py --live
Fixture mode makes no network request and requires no credential. Live mode makes a single call with a 30-second timeout. It does not silently retry or execute any downstream action. For a production queue, add a bounded retry policy for transient failures and a durable review destination.
Expected fixture result
{
  "handler": "deep",
  "generation_executed": false
}
This output is deterministic fixture data, not a measured Jev response. A live model may produce different values and routes. Keep the full returned probability distributions when diagnosing that difference.
Read the probabilities
A Choice winner alone does not reveal ambiguity. Compare its confidence and distribution with the selected label. A Score is an ordered semantic value; use its legend before applying numeric thresholds. A Noul is the probability of yes and has no separate confidence field.
Failure cases and production improvements
Prompt length is not task difficulty. A short legal judgment may need review, while a long formatting task may fit a fast model. Monitor total cost and end-to-end latency: a routing call can cost more than it saves for very simple workloads.
Pin the tested model, log the returned version and rubric revision, and keep a small evaluation set under version control. Re-test after changes to inputs, provider, questions, or policy. Avoid logging sensitive input by default.
Complete code
The downloadable standalone script includes request construction, fixture data, response validation, the decision function, and command-line execution. It uses the direct HTTP API so no SDK dependency is required. For SDK versions of the core ticket request, see Python and JavaScript.
What to test before shipping
- Exact arithmetic selects the deterministic handler.
- Low-confidence routing chooses human review.
- Sensitive input never falls through to an unapproved model.
- No model call occurs merely from parsing an untrusted label.
- Network failures, invalid JSON, and missing fields must never become an automatic action.
- Compare several thresholds on labeled data and record the resulting review volume.